Human-in-the-loop AI, usually shortened to HITL, is a way of designing automated systems so that people retain meaningful control. The machine can search, compare, draft, classify, and recommend at speed; a person sets the objective, inspects consequential outputs, handles ambiguity, and remains accountable for the decision.
For operators, the value is not simply catching an occasional typo. Good human oversight changes the architecture of a workflow. It defines what an agent may do alone, which confidence threshold triggers review, what evidence the reviewer sees, how a decision is recorded, and how corrections improve the next run. The result is useful automation without pretending uncertainty has disappeared.
Agent Oracle treats HITL as an operating discipline rather than a reassuring label. Human review is most valuable where context, money, access, reputation, or irreversible action is involved. Low-risk work can move quickly; high-impact work should pause with enough information for a person to make a real choice.

1. Better accuracy where context changes the answer
AI is strong at pattern recognition and synthesis, but a plausible answer is not automatically the right answer for a particular company. A model cannot know that a renewal is politically sensitive, that a supplier agreement contains a negotiated exception, or that a metric changed definition last quarter unless those facts are supplied and understood.
A reviewer can compare an output with current records, notice when a recommendation conflicts with lived context, and request another pass. This is especially important for sparse or unusual cases, where historical averages can be confidently misleading. Review converts an apparently complete answer into a tested proposal.
2. Clear authority and accountability
An autonomous-looking workflow can blur responsibility: the model generated a recommendation, the software executed it, and nobody can explain who approved the outcome. HITL restores an explicit decision owner. The system records what was proposed, what evidence was available, who approved or changed it, and why.
That trail is useful before anything goes wrong. Teams can audit patterns, compare reviewer decisions, find weak instructions, and demonstrate that important actions were not delegated blindly. Human approval must be substantive, not a decorative click after the system has made reversal impractical.
- Name the person or role with authority to approve the action.
- Show evidence, uncertainty, and alternatives at the review point.
- Preserve the original output and the human decision for later audit.
- Give the reviewer enough time and a genuine ability to stop the workflow.
3. Safer exceptions and escalation
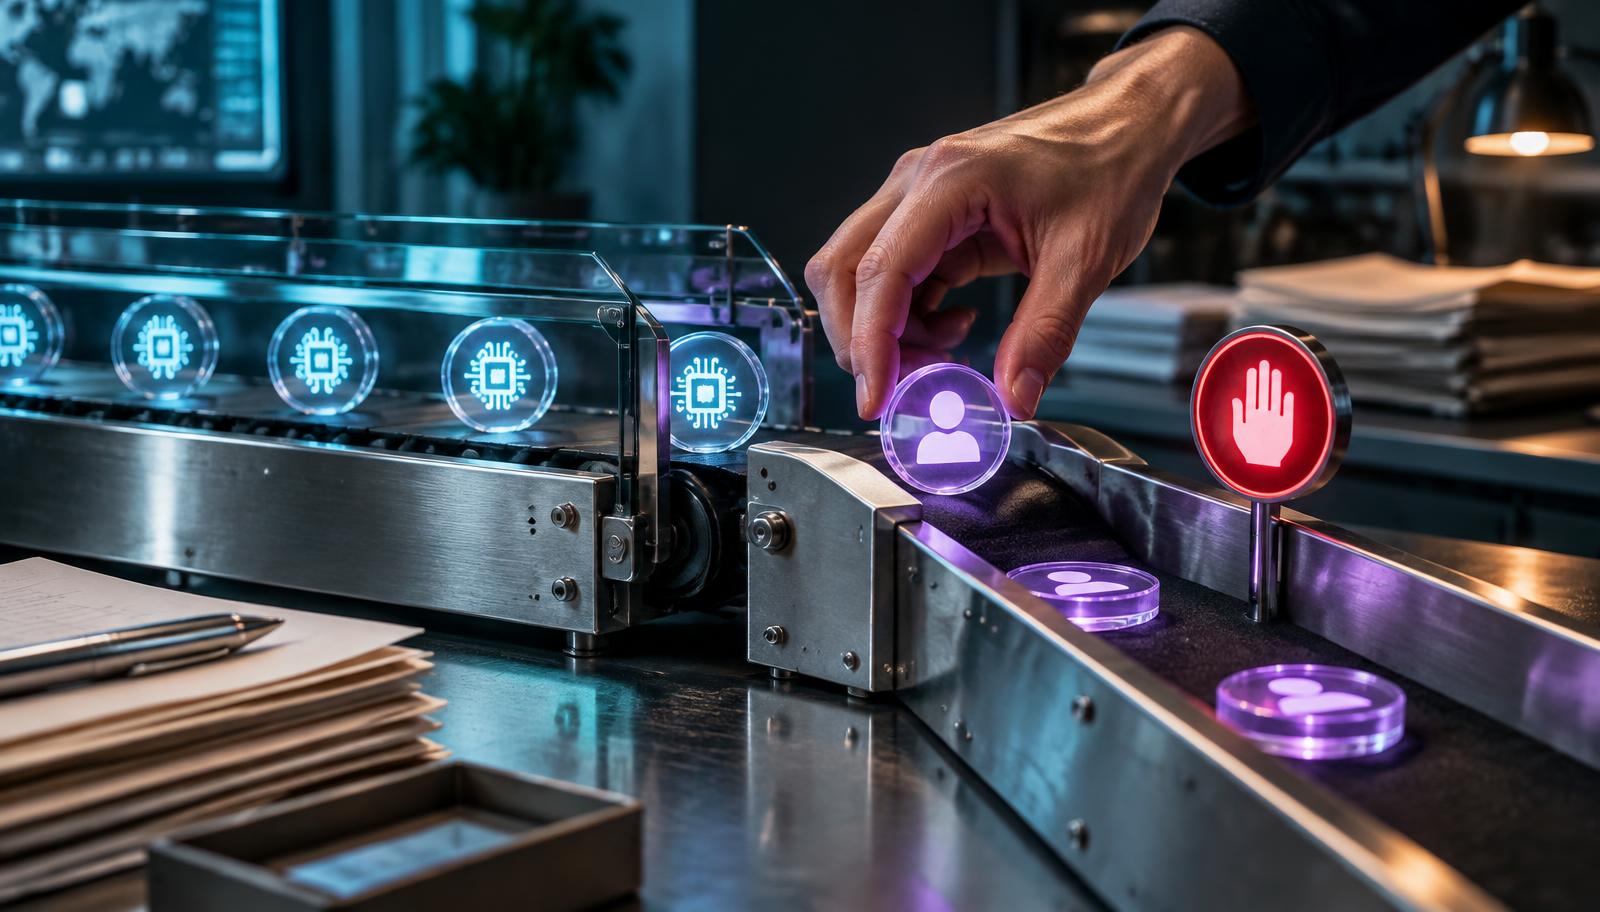
The best automation does not force every case through one path. It recognizes uncertainty and knows when to stop. Low confidence, missing fields, conflicting sources, unusual payment values, permission changes, or sensitive language can all trigger an escalation instead of an improvised answer.
A well-designed handoff includes the history and evidence already gathered. The person should not have to reconstruct the case from scratch. After resolution, the team can decide whether the exception should remain human-only or become a tested rule for future cases.
4. Learning from corrections without automating mistakes
Human feedback is valuable training data only when it is deliberate and reviewed. A correction can reveal a missing policy, an unclear instruction, a weak source, or a genuinely new situation. Capturing the reason matters more than recording that one output was rejected.
Teams should look for repeated patterns before changing a workflow. One hurried approval should not become a permanent rule. Versioned prompts, evaluation sets, sampled audits, and rollback points let improvements accumulate while keeping experimental changes away from live decisions.
5. Proportionate oversight, not a human bottleneck
HITL does not mean manually approving every email or spreadsheet row. That would erase the benefit of automation and train reviewers to click through alerts. Oversight should be proportional: routine, reversible work can be sampled; unusual or high-impact work can require approval; prohibited work should never be delegated.
Useful measures include escalation rate, time to decision, reviewer disagreement, reversals, and harm avoided—not only throughput. If alerts are routinely ignored, the control is failing even if the dashboard reports one hundred percent review.
6. Better adoption because people can challenge the system
Teams are more willing to use automation when they understand its boundaries and can contest its output. A black box that silently acts creates either misplaced trust or defensive avoidance. A reviewable proposal invites a healthier response: inspect the evidence, disagree when necessary, and use the system where it genuinely saves time.
That challenge channel also protects frontline knowledge. People closest to customers and operations often see changing conditions before they appear in data. Recording their reasons for an override turns local insight into evidence for the wider team instead of treating every disagreement as resistance to automation.
Worked example
A practical Agent Oracle review loop
Consider an agent preparing a customer-renewal recommendation. The useful division of labor looks like this:
- 01
Machine preparation
The agent gathers usage, support history, contract dates, and comparable renewals, then proposes options with cited evidence and a confidence level.
- 02
Automatic boundary
Missing data, unusual discounts, legal terms, strategic accounts, or a low-confidence recommendation pause the workflow before any customer contact.
- 03
Human judgment
An account owner considers relationship context, challenges assumptions, changes the recommendation, and records the reason before approving an action.
- 04
Measured learning
The team reviews recurring overrides and updates rules only after testing them against representative cases.

The honest limit of HITL
Human oversight is not evidence that an AI system is weak. It is evidence that the organization understands the difference between computation and responsibility. The strongest workflow gives machines the repetitive work they do well and gives people the authority, evidence, and time needed for judgment.
No review process makes AI infallible. People can miss errors, share biases, or approve too quickly. HITL works when review is designed, measured, challenged, and improved—not when a human name is added to an otherwise autonomous process.