In entertainment, human-in-the-loop AI means the performer, editor, host, or producer remains the director. AI can suggest a clue, generate a guess, organize research, or create alternate lines in seconds. A person decides what belongs in the show, what fits the audience, and when the system should stop.
That distinction matters most in live settings. A response that looks harmless in isolation can reveal a spoiler, flatten a cultural reference, misidentify a real person, or land badly in the room. Human judgment adds knowledge the model cannot read from a prompt: timing, tone, community expectations, and the emotional temperature of the moment.
CineMind uses HITL as a creative control surface. The goal is not to sand away surprise. It is to preserve the fun of unpredictable AI while keeping a human hand on pacing, boundaries, and publication.

1. Creative direction stays with the creator
Generative systems can produce many options, but abundance is not taste. A creator recognizes which idea serves the scene, which clue is too obvious, which joke breaks the character, and which unexpected turn is worth keeping. Selection, sequencing, and restraint create the experience.
A strong loop lets the machine propose rather than dictate. The host can accept, edit, regenerate, or discard, and those choices remain visible. This protects the creator's voice from becoming an average of whatever the model has seen before.
2. Live safety needs an immediate stop button
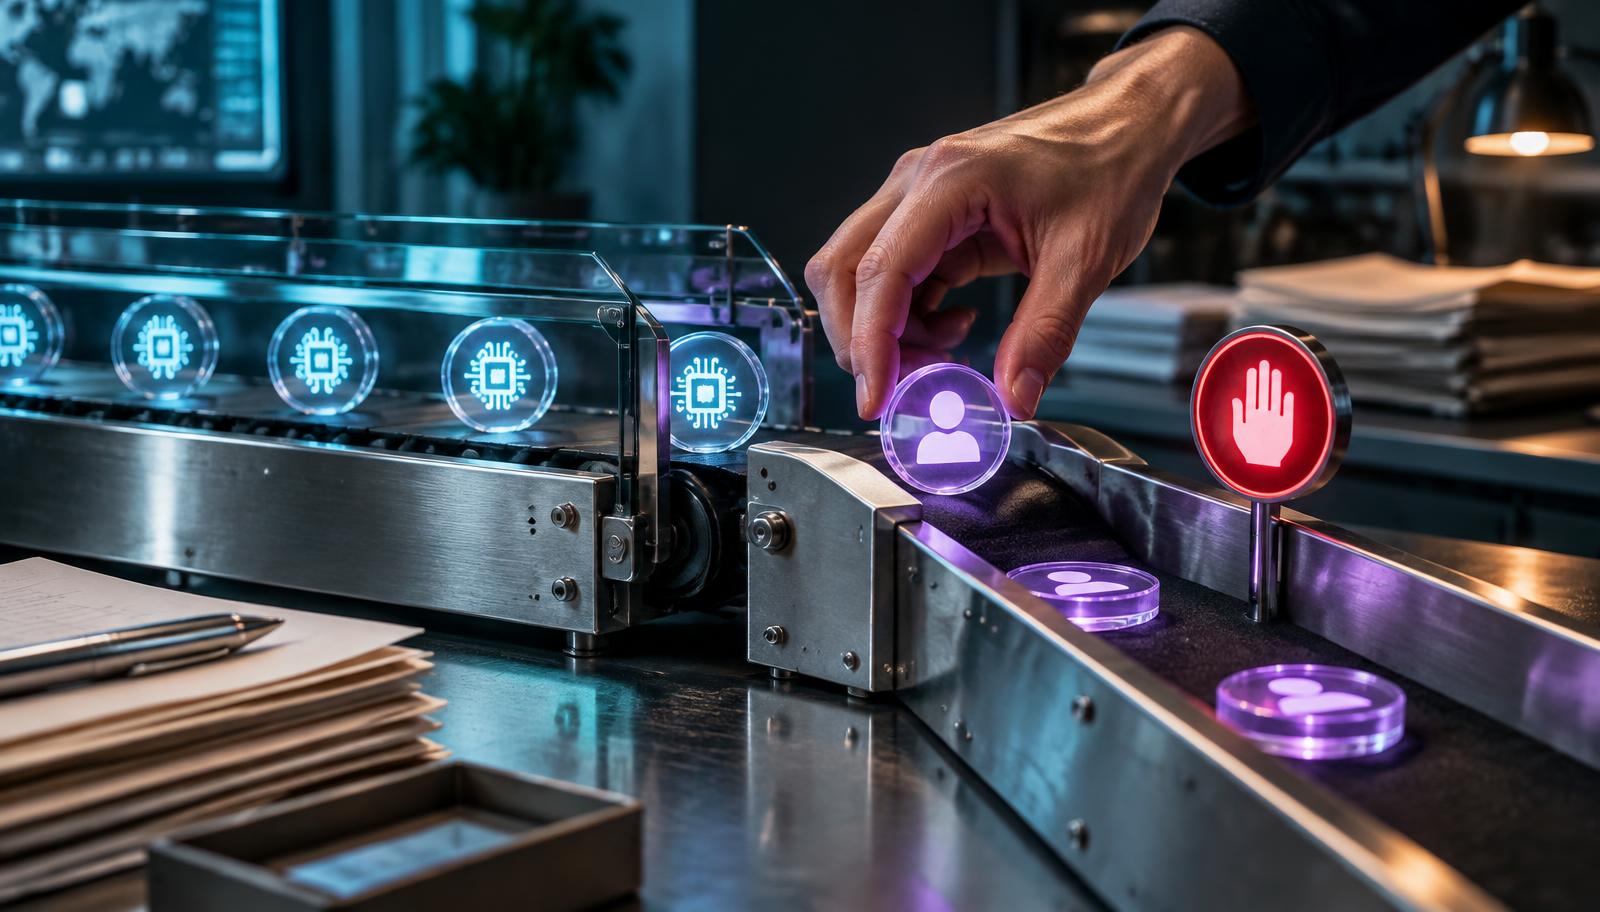
Recorded content offers an edit; live content does not. That makes interruption a first-class feature. A moderator needs to mute output, skip a topic, lock a title, delay a reveal, or end a segment without waiting for a technical operator.
The safest design combines preventive boundaries with active supervision. Filters can block known hazards, but people detect emerging context: chat has changed mood, a guest is uncomfortable, or a seemingly ordinary clue now points to a sensitive event. Human attention covers the gap between a rule and a moment.
- Keep mute, skip, and end-session controls visible during the broadcast.
- Treat recent-release spoilers and real-person claims as escalation categories.
- Give moderators the exact output and conversation context, not a vague alert.
- Review reported moments after the stream and record the corrective action.
3. Audience context improves relevance
A model may know a franchise but not this community's running jokes, spoiler tolerance, age range, or preferred pace. Hosts carry that local knowledge. They can steer clues toward the audience in front of them and reject material that is technically relevant but socially wrong for the room.
This also improves accessibility. A person can notice that clues rely too heavily on visual detail, that captions are moving too fast, or that cultural shorthand excludes part of the audience. Oversight is not only protection; it is adaptation.
4. Fair play and explainable outcomes
Games feel unfair when rules shift invisibly. HITL gives a host a way to challenge an implausible guess, correct misunderstood input, or void a round affected by a system fault. The reason should be explained to the audience rather than hidden behind the authority of an algorithm.
Review data can expose recurring imbalance: a category that is consistently easier, a clue pattern that favors one fandom, or names the speech system repeatedly mishears. That evidence supports rule changes without rewriting history after a single unpopular result.
5. Better improvement after the stream
The most useful feedback happens after the adrenaline drops. Producers can review flagged exchanges, audience reports, skips, and manual corrections together. They can distinguish a model problem from a poor prompt, incomplete title data, unclear moderation guidance, or a control that was too slow to reach.
Changes should be tested in rehearsal before they reach a live audience. A loop that learns from every complaint without review can become erratic; a loop that never changes repeats the same mistakes. Human evaluation provides the middle path.
6. Trust grows when correction is visible
Audiences do not expect a live system to be perfect, but they do notice whether a creator owns the outcome. A quick explanation, a fair reset, and a visible route for reporting a bad response are more credible than pretending the automation cannot fail. The human role includes communicating the correction, not merely pressing a hidden control.
Visible accountability also prevents the AI label from becoming an excuse. The production remains responsible for what it chooses to broadcast. That responsibility encourages better rehearsal, clearer house rules, and safer defaults while preserving the spontaneous energy that made the format worth watching.
Worked example
A practical CineMind live loop
Imagine a creator running an audience guessing segment. A resilient production divides the work this way:
- 01
Machine preparation
CineMind interprets answers, proposes the next clue, and estimates confidence while respecting the selected titles and spoiler settings.
- 02
Automatic boundary
Sensitive real-person claims, restricted titles, uncertain speech input, or a likely spoiler pause instead of going straight to the overlay.
- 03
Human direction
The host chooses the clue, adjusts tone, skips an awkward path, or explains why a round is being reset.
- 04
Post-show learning
Flagged moments and audience reports are reviewed before guardrails or game rules change.

The honest limit of HITL
The point of human oversight in entertainment is not to make every moment safe and predictable. It is to make experimentation recoverable. Creators can take risks because they can interrupt, explain, and correct the system when surprise becomes harm or confusion.
A human can still make the wrong call, and a fast-moving chat can overwhelm any moderator. HITL reduces risk; it does not erase it. Clear controls, rehearsed escalation, audience reporting, and honest corrections make the loop real.